

Introduction
You hired a rescue team to fix broken features. Three weeks in, they come back with a proposal to change the database schema. This feels like scope creep. You wanted bug fixes, not surgery on the foundation.
Sometimes that instinct is right. Developers unfamiliar with an existing design can mistake unfamiliarity for dysfunction, and a rescue team new to your codebase is exactly the kind of team prone to that mistake, as the Simple Talk refactoring process points out. But sometimes the schema really is the problem, and every surface fix your team ships is a patch on top of a structural defect that will keep generating new bugs. The job is telling these two situations apart before you approve weeks of data-layer work.
What you’ll learn
- The diagnostic signals that justify a schema-level look
- When patching is genuinely the safer near-term call
- Deciding between full rebuild, layer refactor, or continued patching
- What to ask before approving the schema work
The diagnostic signals that justify a schema-level look
Ask your rescue team to show you evidence, not opinions. A credible rescue audit produces specific technical findings tied to delivery impact, not general discomfort with the existing design, according to Idea Maker’s rescue guide. For the database layer specifically, three signals carry real diagnostic weight.
N+1 query patterns. If a single page load triggers dozens or hundreds of individual queries because related data was never modeled with proper joins or eager-loading in mind, that is not a code style problem you can patch in the application layer forever. It is evidence the schema was not designed with the app’s actual access patterns in mind.
Missing indexes on frequently filtered or joined columns. This one is often fixable without a schema refactor, so treat it as a separate line item. If your team bundles
Related Zenveus resource: Code Rescue insights.
When patching is genuinely the safer near-term call
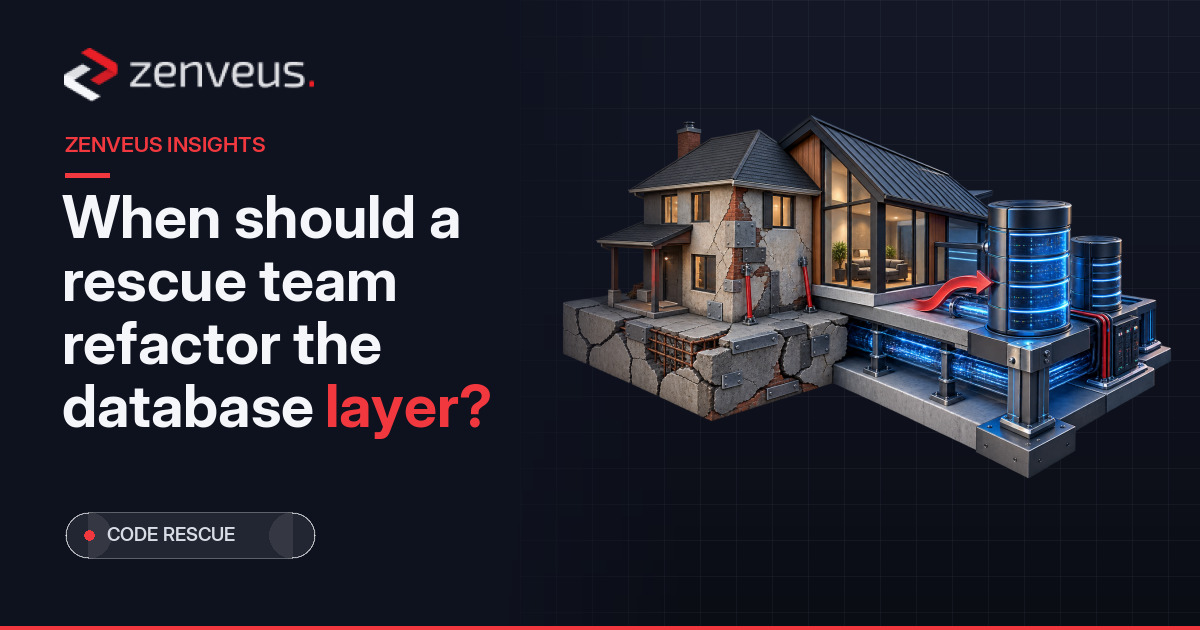
Not every rescue engagement should touch the schema, even when the schema has real problems. The core tradeoff is that a schema refactor cannot be isolated. Any structural change to the database must be accompanied by changes in every layer that reads or writes that data, per this Stack Exchange analysis of team database refactoring. That means a schema change is never just a schema change. It is a schema change plus every query, every ORM model, every API contract, and every downstream integration that assumes the old shape.
If your product is mid-launch, mid-fundraise, or mid-customer-migration, that blast radius may be unacceptable right now regardless of how compromised the schema is. Patching gives you time. It does not remove the underlying debt, but it buys runway to schedule the deeper work when the business can absorb the disruption. The rescue team’s job at that point is to document exactly which patches are temporary and what the honest cost of continued patching looks like, so the decision to defer is made with eyes open rather than by default.
The coordination cost is also organizational, not just technical. Any team refactoring a shared database should inform and get buy-in from every other team affected by the change before starting, per this discussion of database refactor coordination. If your rescue team cannot name who else touches these tables, that is itself a red flag about how ready the org is for the change, independent of the schema’s technical merits.
Deciding between full rebuild, layer refactor, or continued patching
Once you have confirmed the schema is the real structural problem, the next decision is scope. A full application rebuild is rarely necessary just because the data model is wrong. When the data model is the structural issue but the API and frontend layers still function adequately, refactoring the data layer and migrating to it incrementally is faster and lower-risk than rebuilding the entire system, according to this founder-focused rebuild-versus-refactor framework.
The caution runs the other way too. If the core abstractions in your database do not match how the business actually operates, a common failure mode in MVP-stage products, every feature built on that model inherits the mismatch, per Kanopy’s analysis of MVP-to-scale transitions. Refactoring inherited code with no documentation and no tests is often slower than founders expect, which is exactly why a rescue team should scope the refactor narrowly: fix the data layer’s boundaries first, keep the rest of the system stable, and resist the urge to redesign everything the schema touches in one pass.
Practically, this means asking your rescue team for a phased plan: which tables change first, which application code adapts alongside each change, and what the rollback path looks like if a migration step fails partway through production traffic. If they cannot answer those questions with specifics, they have not scoped the work; they have identified a problem without a plan.
Use a structured rebuild-or-refactor framework to pressure-test their recommendation against your own read of the codebase, and run the numbers through a cost-to-fix calculator before signing off on scope.
What to ask before approving the schema work
Database refactoring is disruptive even under ideal conditions. Teams following iterative, agile methods still find it culturally and practically difficult once organizational friction is factored in, per AgileData’s essay on database refactoring in agile environments. Going in with a clear checklist protects you from both over-approving unnecessary surgery and under-approving work your product genuinely needs.
- Has the team shown concrete evidence (query logs, index analysis, foreign-key inconsistencies) rather than general dissatisfaction with the existing design?
- Have they confirmed the current schema doesn’t already reflect a deliberate, correct decision they simply don’t have context on?
- Is the proposed change scoped to the tables actually causing failures, or has it expanded to a full redesign?
- Do they have a plan for updating every application layer that reads or writes the affected data, not just the schema itself?
- Who else depends on these tables, and have those stakeholders been looped in?
- What is the rollback plan if a migration step fails in production?
Rescue teams that treat database access as scattered, untestable, and undocumented often recommend refactoring the data access layer early precisely because it unblocks everything downstream, according to this CTO rescue playbook. If your team’s recommendation matches that pattern with specific evidence attached, the schema work is probably earning its cost. If it’s vague, unscoped, or missing a migration plan, push back and ask for the diagnostic detail first.
NEXT STEP
Make the rebuild decision with clearer thresholds
Use a practical framework to compare remediation risk, architectural constraints, and the cost of starting again.
Open the Rebuild or Refactor Guide